#1 Apache Kafka Meetup in São Paulo/Brazil

Tuesday, Dec 11, 2018 | 3 minute read

Ricardo Ferreira

During the week of Dec 2th I had the pleasure of visiting São Paulo/Brazil, a place that I once called home. It has been almost 5 years that I left that city to live abroad – and every time I go there its inevitable not to miss certain things.

I went down there to participate of the Google Cloud Summit event, and make sure that developers using GCP would be aware of Confluent’s Apache Kafka as a service know as Confluent Cloud. It was amazing to share this information with them, since most of them was working (or planning to work) with huge amounts of data in the Cloud and Kafka is certainly the right way to do it.

But what would be the value of a Developer Advocate that speaks Portuguese and visits Brazil that not gives a talk in a local meetup, right? Hence why I used my time there to give a presentation in what was the #1 official Apache Kafka meetup in the region. And boy… the results couldn’t be better.
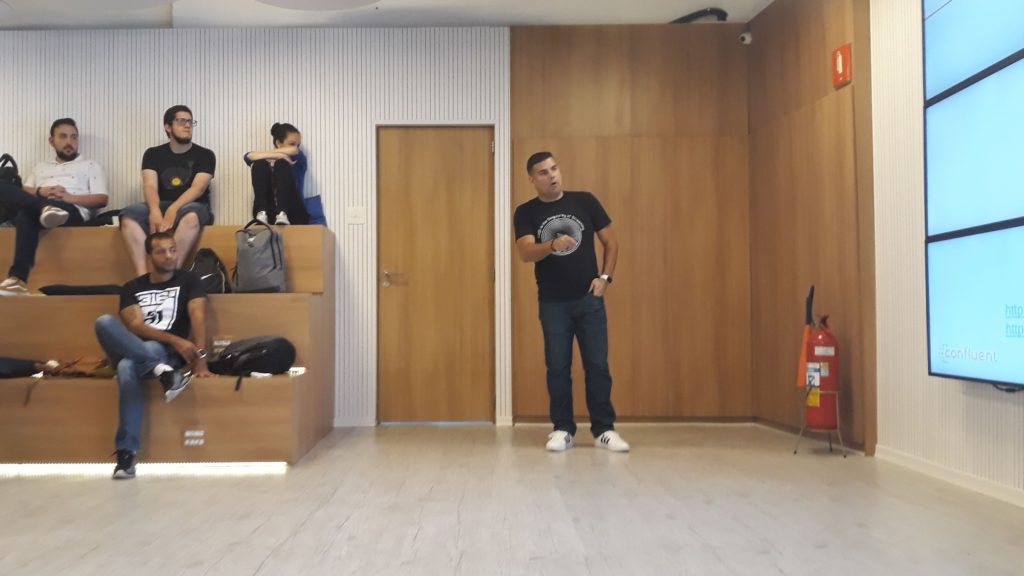
Not only I’ve meet nice and smart people (hey, this is Brazil we’re talking about, nothing new here) but I was surprised with the amount of great use cases I have found in there. People using Kafka in lots of cool ways, whether if is to handle high volume of data or; by using some of the cool stuff that we have been working on lately such as Connect, Streams API and KSQL.
But what I was really surprised is how some people are truly using Kafka as a persistent storage and single-source-of-truth of data , as a layer that holds data before delivering to the external systems. This is the proof that Brazil is certainly of the countries that we should invest more time: they literally got the point of what a Streaming Data Platform is.
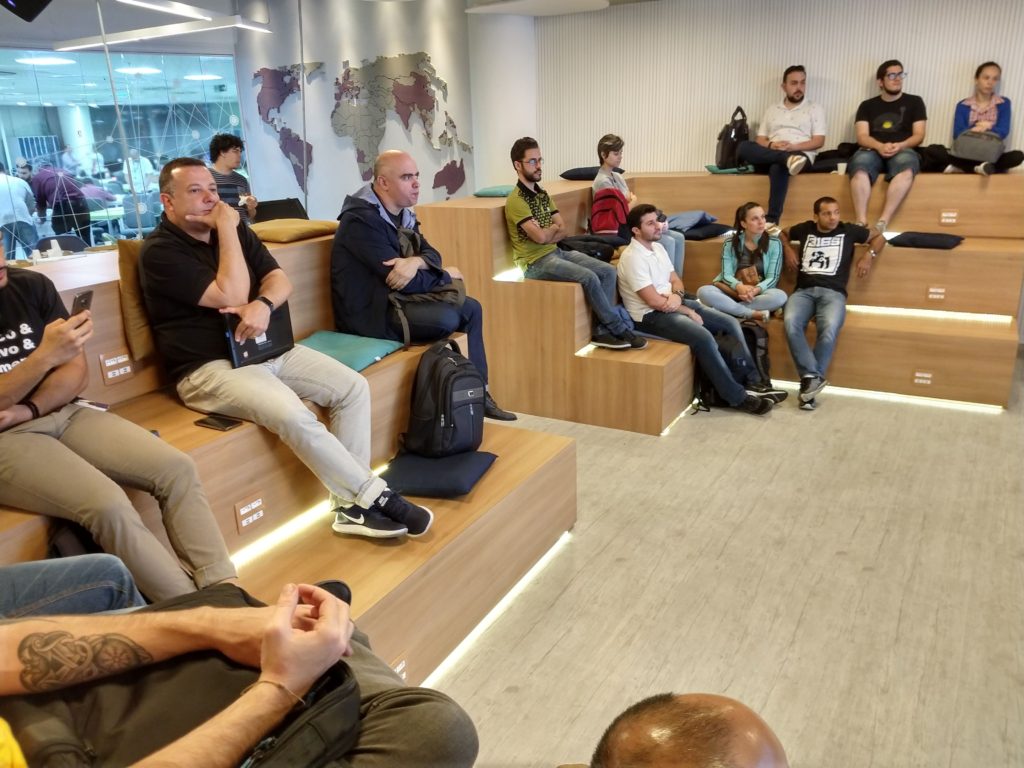
The meetup itself was very fun. I was able to share what I wanted to say about Kafka, in which I tried to calibrate the knowledge of the people present. Certainly; there was two types of people: the ones that only had heard what Kafka was and the ones that knew a lot about the subject – with some of them possessing deep understanding of Kafka’s internals. FYI, the slide deck from the meetup can be found here.
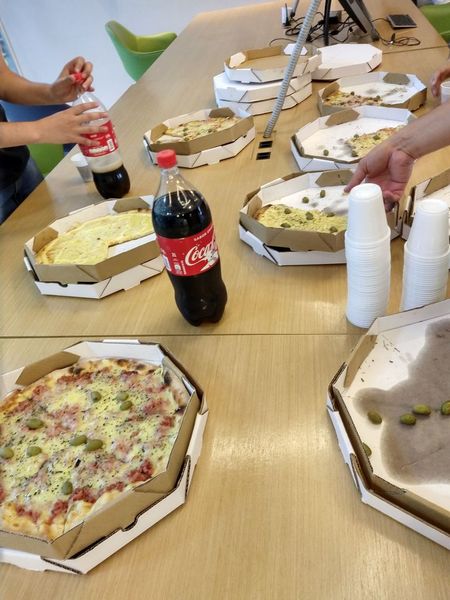
I am looking forward to get back there as soon as possible, to continue my journey of letting people know what Apache Kafka can do. But I left the country with a smile in the face knowing that there are people there that knows their s***hit, and that’d be very good at helping us to spread the word. That gives me a fix of feelings; that includes satisfaction and proud, all at the same time.

A special thanks to Breno Barros and Diego Irismar for helping organizing this meetup, you guys made something really great considering the short amount of time given. It is all about the community, success is never a one-man’s-action.
© 2018 - 2026 Ricardo Ferreira

Search is powered by Pagefind. Just hit CTRL+K or CMD+K to start searching.

Powered by Hugo with Dream and Devrel themes.

Open Source

I contribute to LangChain4j, an idiomatic open source Java library for building LLM-powered applications on the JVM. Recent work includes adding native vector search embedding stores so developers can build RAG, recommendation engines, and AI memory systems.

I also ported RedisVL to Go, an open source, AI-native client that brings vector search, semantic caching, LLM memory, semantic routing, rerankers, and an MCP server to the Redis ecosystem for Golang developers.

Public Speaking

I’ve been speaking at conferences since 2008 and doing it full time as part of my work with DevRel since 2018. My talks go deep on the systems I build with: distributed systems and event streaming, AI engineering and vector search, and the data infrastructure that has to hold up when the demo ends and production begins. Some of the events I’ve spoken at include AWS re:Invent, Microsoft Ignite, Google Cloud Next, KubeCon, Oracle OpenWorld, QCon, Strange Loop, Kafka Summit, Pulsar Summit, JavaOne, DevNexus, JFokus, JNation, and All Things Open.

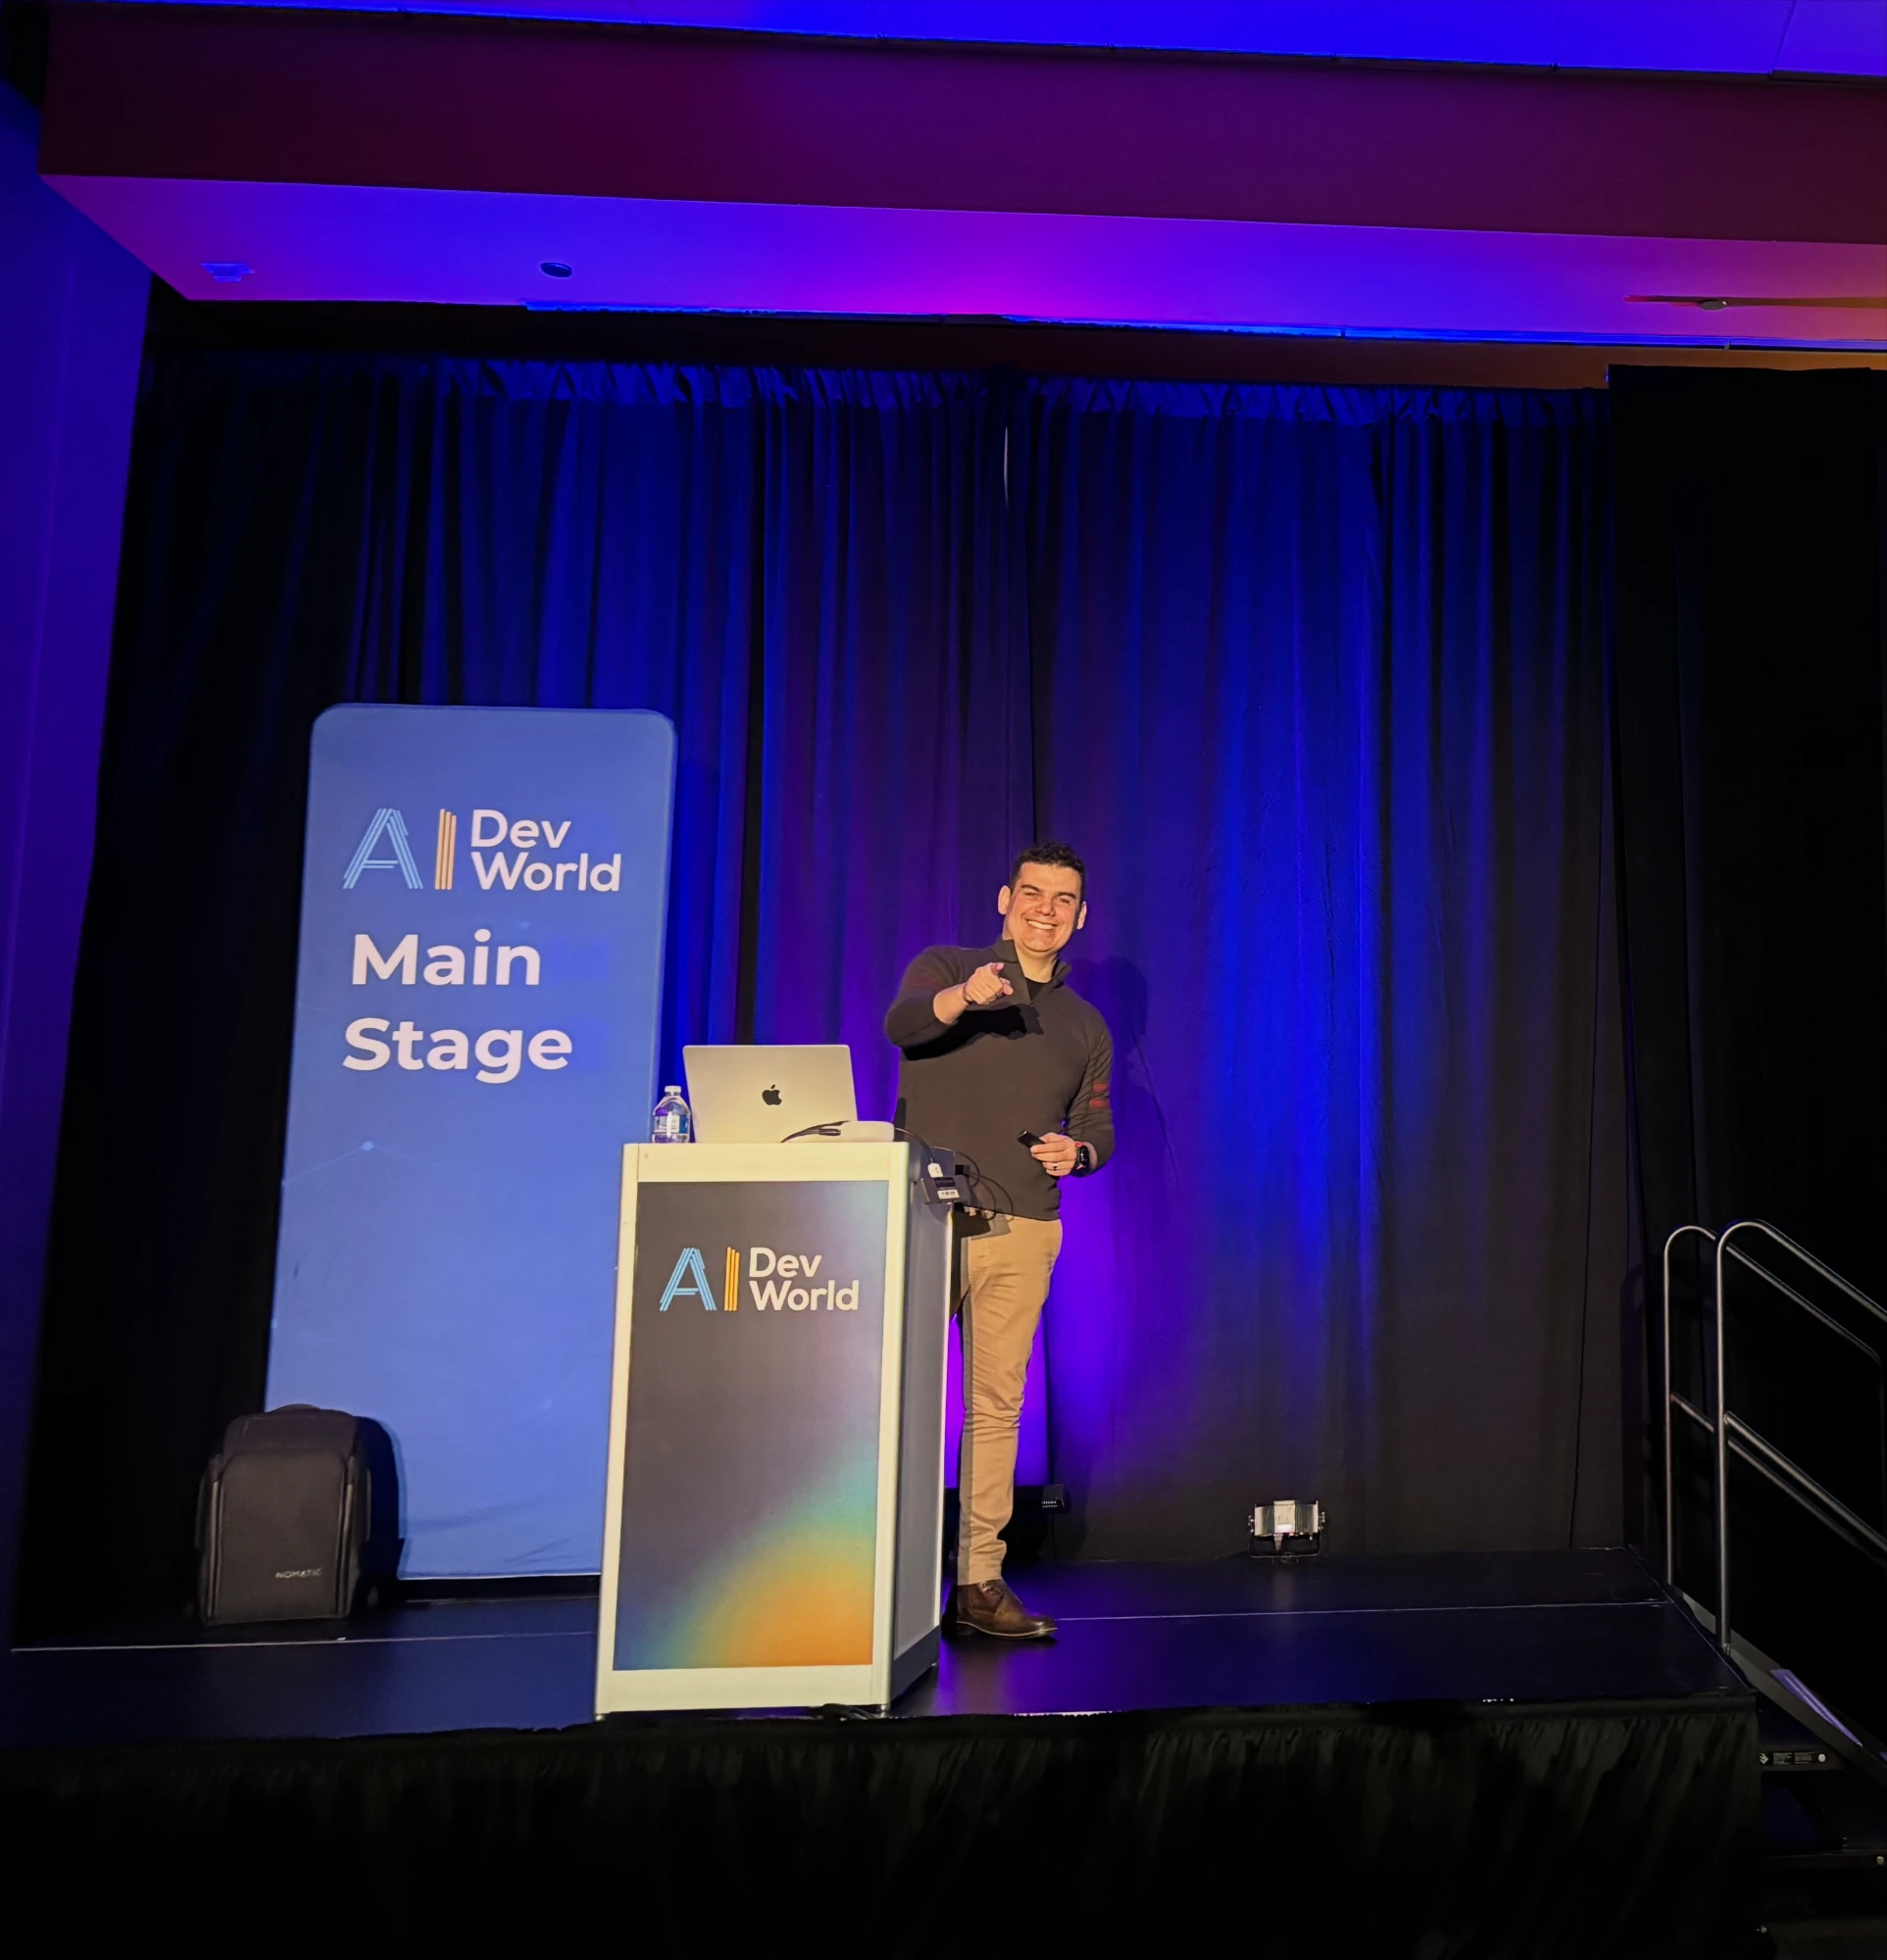
Ricardo Ferreira presenting on the main stage at AI DevWorld
On the main stage at AI DevWorld

You can find my upcoming and past talks on my speaking calendar. Recordings also live on my YouTube channel, and the code I write for talks, demos, and workshops is on my GitHub.

Consulting and Professional Services

If you’d like to hire me as a consultant for your projects, speak at your event, or lead a hands-on workshop for your team, contact me at riferrei@riferrei.com. I can understand the scope of your request and provide a free estimate.

Who am I?

I work at the intersection of AI, data infrastructure, and distributed systems, turning complex technology into things developers can understand and products users love.

Lately, that means hands-on AI engineering: building vector search, semantic caching, agent memory, and RAG into the data layer, and figuring out how to make AI agents secure enough to ship. I contribute to open-source projects like LangChain4j and RedisVL for Golang.

The AI-native work isn’t a pivot. It draws on the same systems-design foundation I’ve built for 20+ years: designing data systems for scale, moving data fast, watching where systems break; now applied to vectors and agents. I have worked on RDBMS and Big Data at Oracle; event streaming with Apache Kafka and Apache Flink at Confluent; observability at Elastic; AI and developer tooling at AWS; and NoSQL and vector stores at Redis. That foundation is exactly what separates AI demos that work on stage from AI systems that survive production.

Social Links