Microservices promise agility and scalability, but the same distribution that makes them powerful can also make them fragile and hard to operate. In this playful yet practical talk, common anti-patterns and mistakes that lead teams to ’lose’ their microservices are explored—from poor service boundaries and chatty communication to missing observability—along with the practices that keep distributed systems healthy and resilient.
I contribute to LangChain4j, an idiomatic open source Java library for building LLM-powered applications on the JVM. Recent work includes adding native vector search embedding stores so developers can build RAG, recommendation engines, and AI memory systems.
Public Speaking
I’ve been speaking at conferences since 2008 and doing it full time as part of my work with DevRel since 2018. My talks go deep on the systems I build with: distributed systems and event streaming, AI engineering and vector search, and the data infrastructure that has to hold up when the demo ends and production begins. Some of the events I’ve spoken at include AWS re:Invent, Microsoft Ignite, Google Cloud Next, KubeCon, Oracle OpenWorld, QCon, Strange Loop, Kafka Summit, Pulsar Summit, JavaOne, DevNexus, JFokus, JNation, and All Things Open.
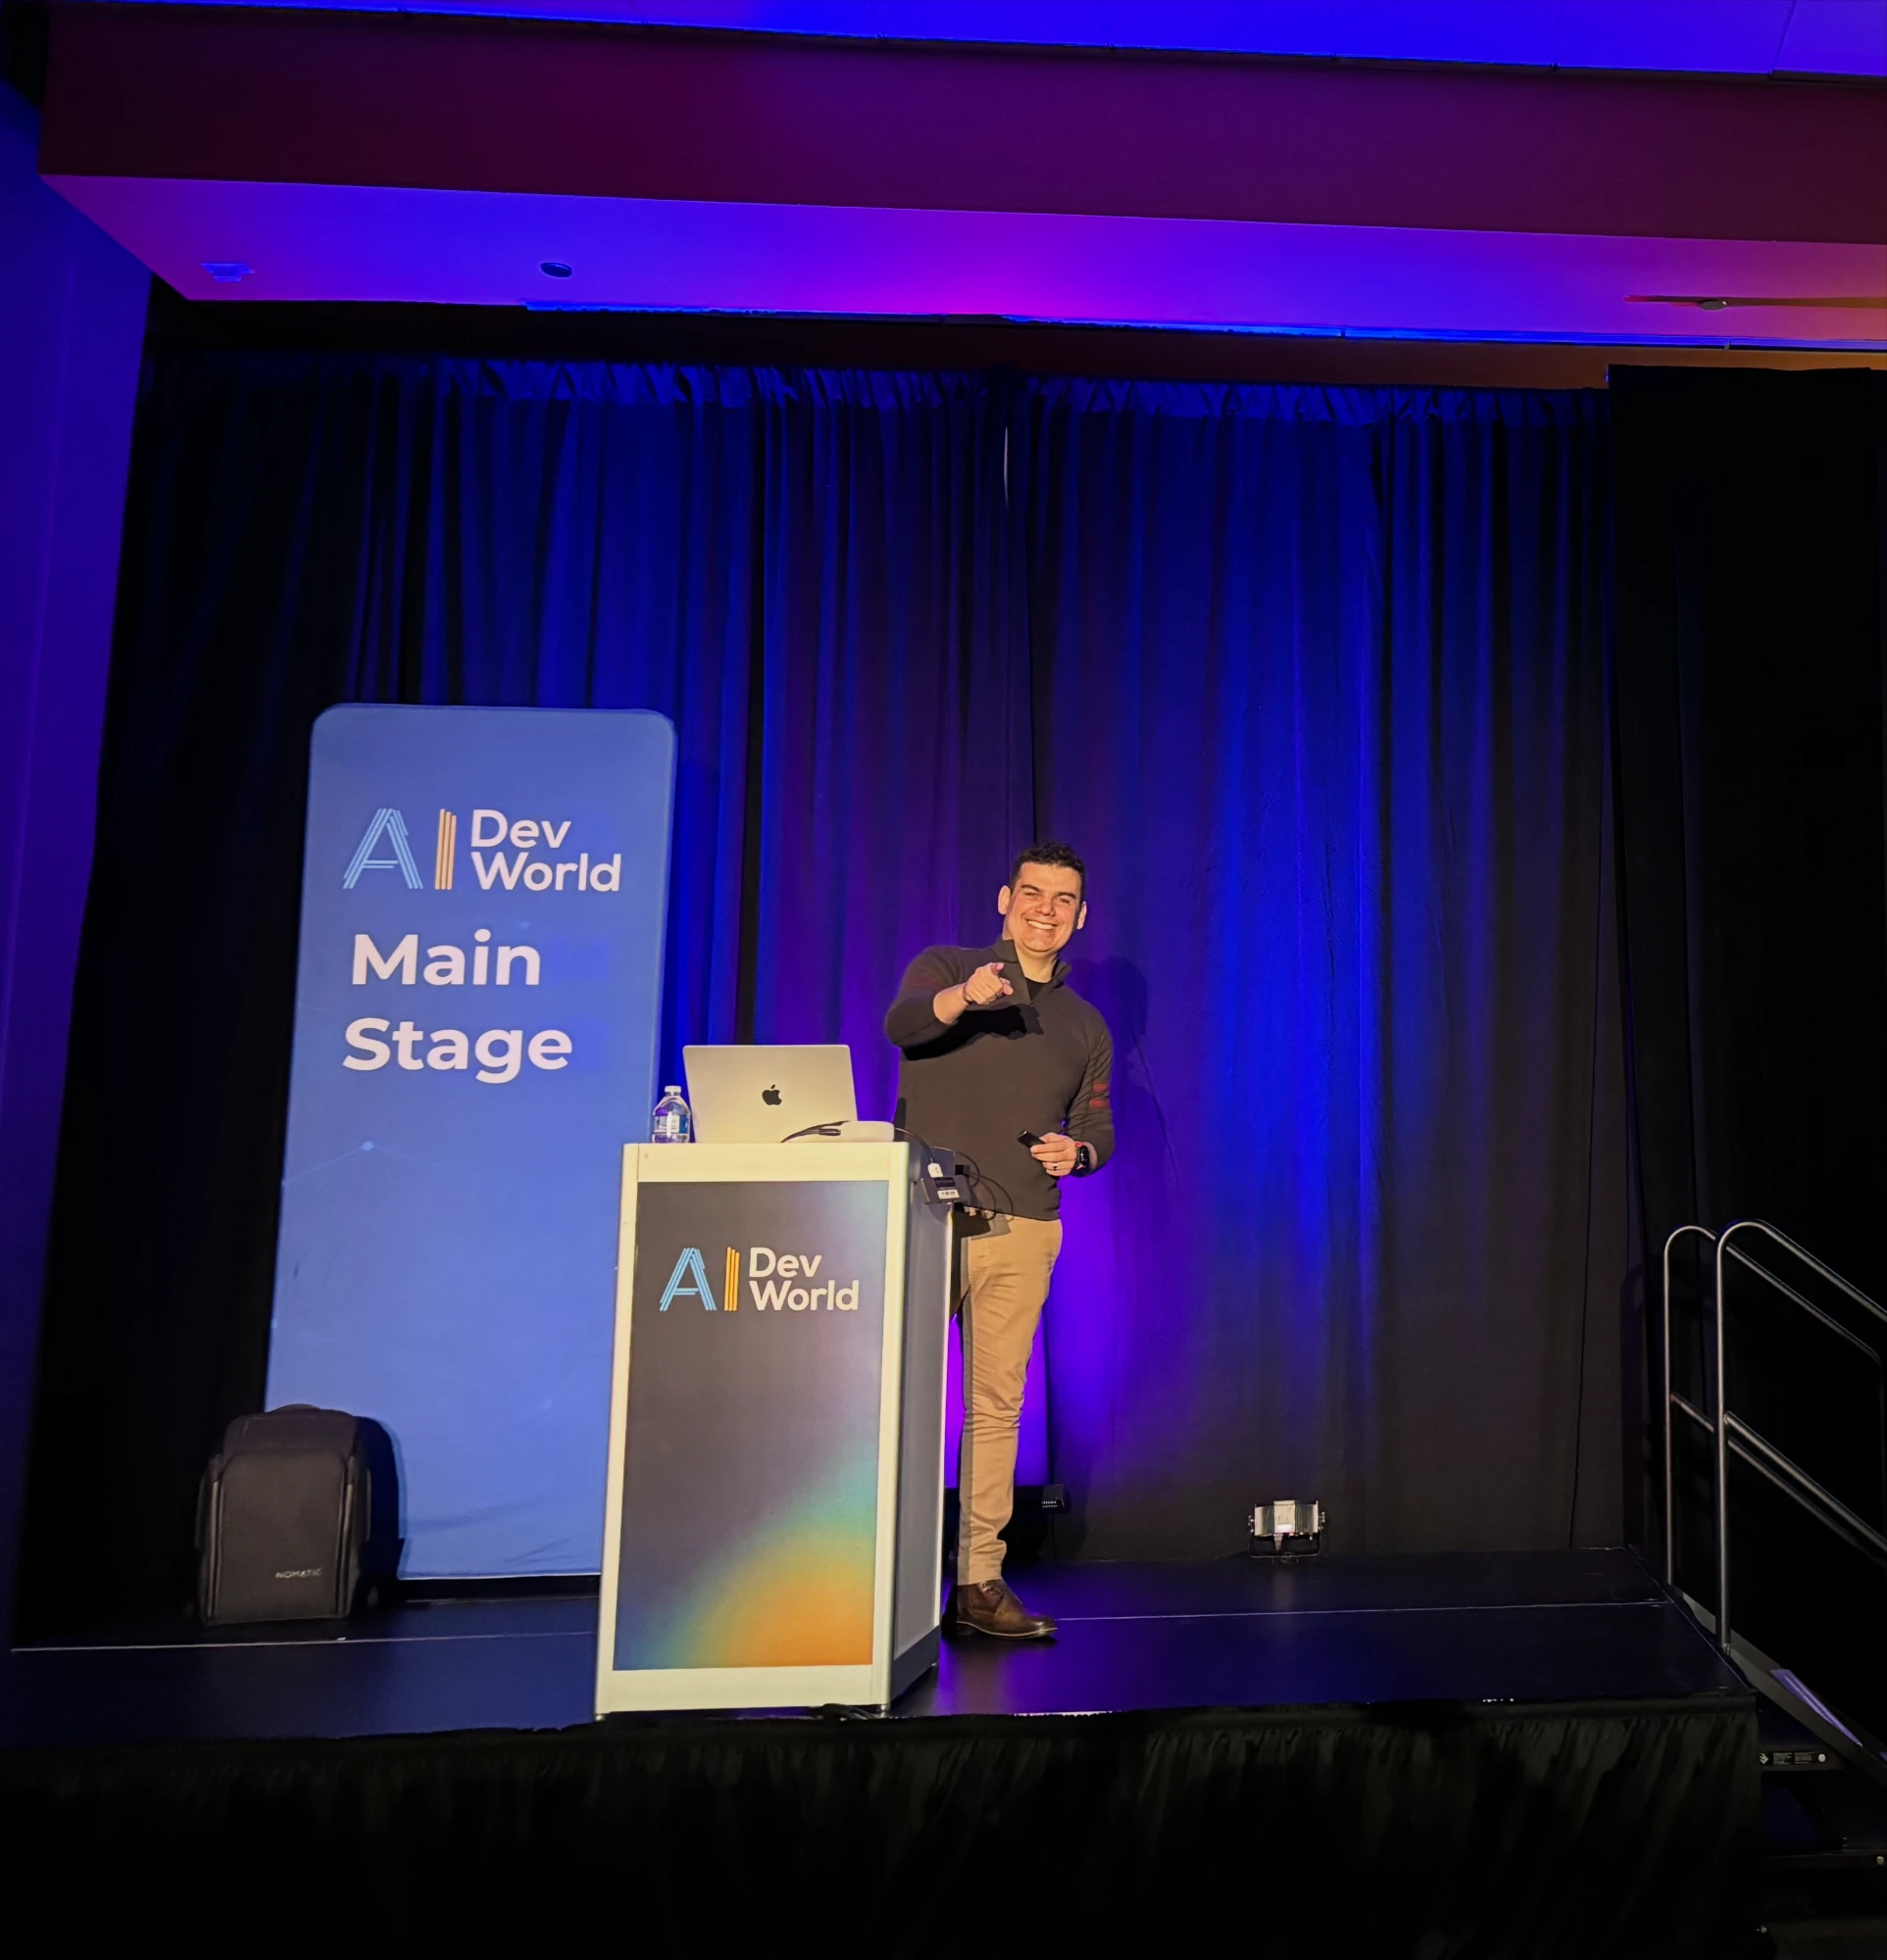
On the main stage at AI DevWorld
You can find my upcoming and past talks on my speaking calendar. Recordings also live on my YouTube channel, and the code I write for talks, demos, and workshops is on my GitHub.
Consulting and Professional Services
If you’d like to hire me as a consultant for your projects, speak at your event, or lead a hands-on workshop for your team, contact me at riferrei@riferrei.com. I can understand the scope of your request and provide a free estimate.
Who am I?
I work at the intersection of AI, data infrastructure, and distributed systems. In practice, that means hands-on AI engineering: building vector search, semantic caching, agent memory, and RAG into the data layer, and figuring out how to ship AI agents securely. I also contribute to the LangChain4j open-source project.
The AI-native work isn’t a pivot, though. It draws on the same systems-design foundation I’ve built for 20+ years: designing data systems for scale, processing fast data, watching where systems break; now applied to vectors and agents. I have worked on RDBMS and Big Data at Oracle; event streaming with Apache Kafka and Apache Flink at Confluent; observability at Elastic; AI and developer tooling at AWS; and NoSQL and vector stores at Redis.
This foundation is exactly what separates AI demos that work on stage from AI systems that survive production.