Ricardo Ferreira
Ricardo Ferreira
Building with AI, Data Infrastructure, and Distributed Systems
  • Search
  • Archives
  • Talks
  • Calendar
  • About me
  • All Categories
  • All Tags
  • RSS

The Right Number of Partitions for a Kafka Topic

Devnexus 2023 – Atlanta 🇺🇸

Apr. 2023
Ricardo Ferreira
Ricardo Ferreira

Abstract

Every technology has that key concept people struggle with, and for Apache Kafka the winner is how many partitions to set for a topic. Sizing partitions wrongly affects storage, parallelism, durability, and how much load Kafka can handle, and while it is often treated as an infrastructure decision left to Ops teams, it is really an architectural design decision that even affects how much code you write. This session peels off the concept of partitions from the perspective of the cluster and its clients, explains the formula to decide how many partitions a topic should have, and shows how to spot a poor decision when you see one.
Previous page Testing Terraform Providers using TestContainers for Go
Next page The Right Number of Partitions for a Kafka Topic
Gave 2 talks at Devnexus 2023
  • 2023-04-05 en The Right Number of Partitions for a Kafka Topic
  • 2023-04-04 en The Right Number of Partitions for a Kafka Topic

© 2018 - 2026 Ricardo Ferreira

Search is powered by Pagefind. Just hit CTRL+K or CMD+K to start searching.

Powered by Hugo with Dream and Devrel themes.

Open Source

I contribute to LangChain4j, an idiomatic open source Java library for building LLM-powered applications on the JVM. Recent work includes adding native vector search embedding stores so developers can build RAG, recommendation engines, and AI memory systems.

Public Speaking

I’ve been speaking at conferences since 2008 and doing it full time as part of my work with DevRel since 2018. My talks go deep on the systems I build with: distributed systems and event streaming, AI engineering and vector search, and the data infrastructure that has to hold up when the demo ends and production begins. Some of the events I’ve spoken at include AWS re:Invent, Microsoft Ignite, Google Cloud Next, KubeCon, Oracle OpenWorld, QCon, Strange Loop, Kafka Summit, Pulsar Summit, JavaOne, DevNexus, JFokus, JNation, and All Things Open.

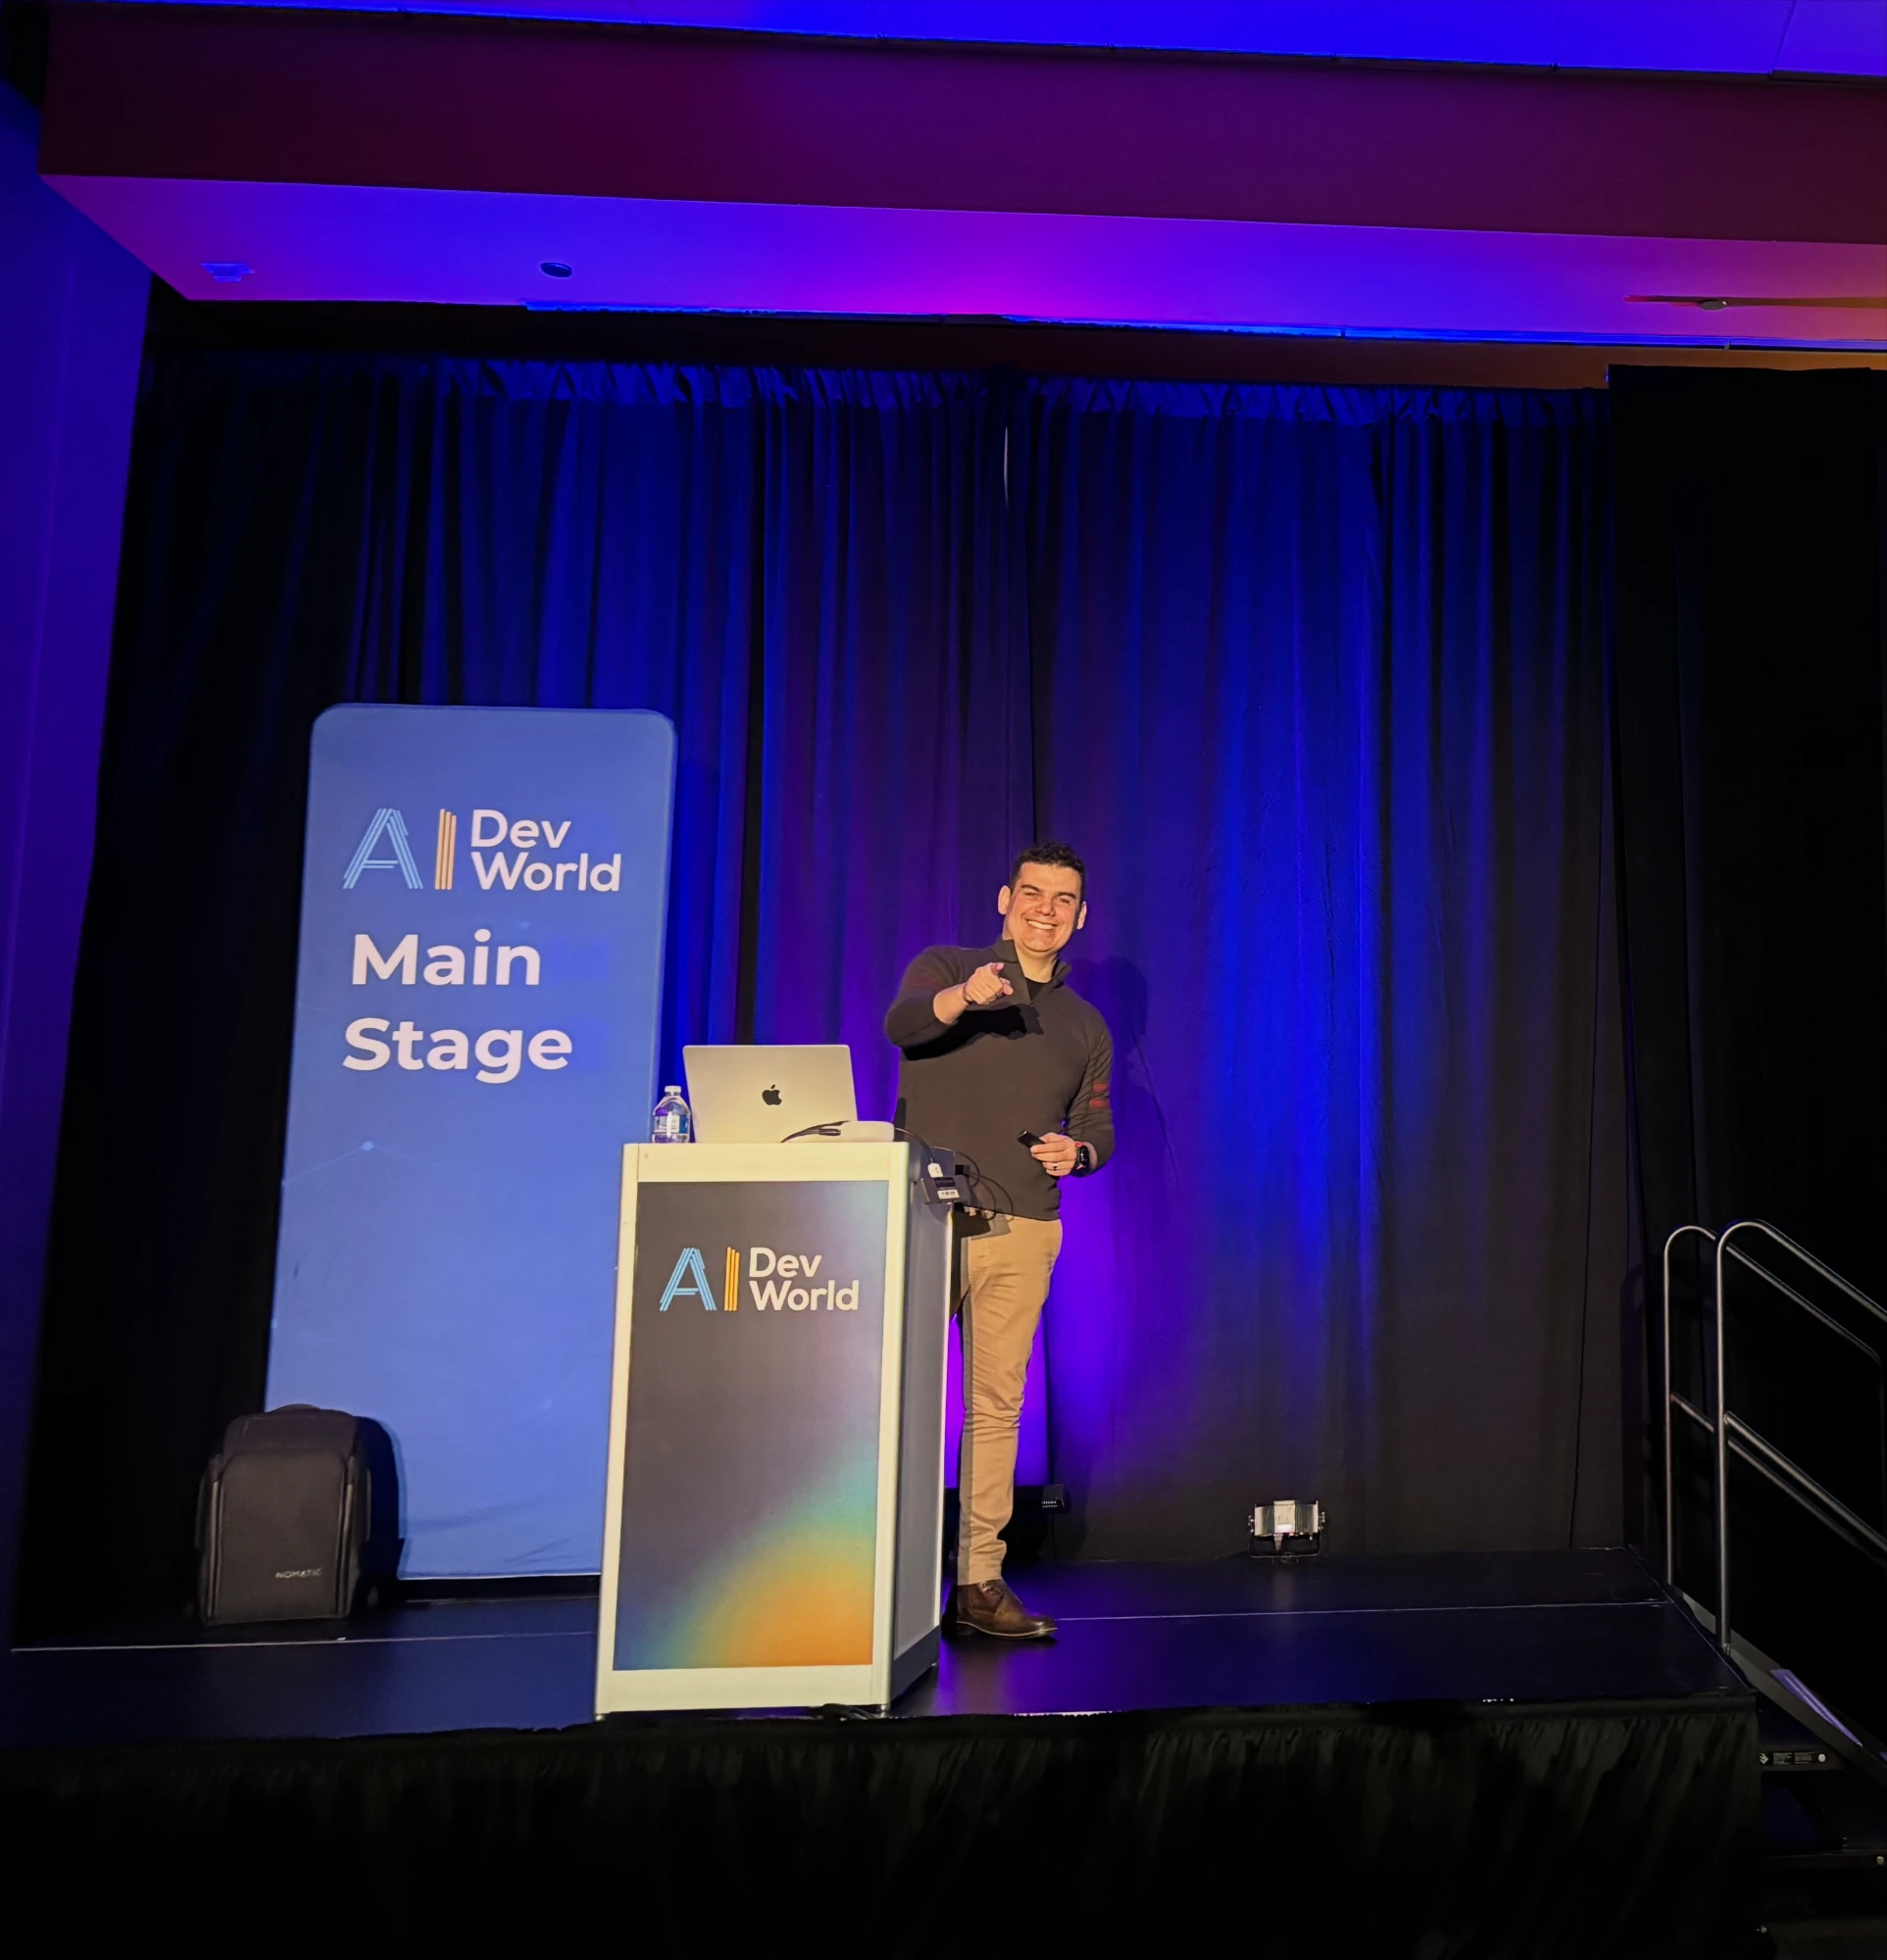
Ricardo Ferreira presenting on the main stage at AI DevWorld
On the main stage at AI DevWorld

You can find my upcoming and past talks on my speaking calendar. Recordings also live on my YouTube channel, and the code I write for talks, demos, and workshops is on my GitHub.

Consulting and Professional Services

If you’d like to hire me as a consultant for your projects, speak at your event, or lead a hands-on workshop for your team, contact me at riferrei@riferrei.com. I can understand the scope of your request and provide a free estimate.

Who am I?

I work at the intersection of AI, data infrastructure, and distributed systems. In practice, that means hands-on AI engineering: building vector search, semantic caching, agent memory, and RAG into the data layer, and figuring out how to ship AI agents securely. I also contribute to the LangChain4j open-source project.

The AI-native work isn’t a pivot, though. It draws on the same systems-design foundation I’ve built for 20+ years: designing data systems for scale, processing fast data, watching where systems break; now applied to vectors and agents. I have worked on RDBMS and Big Data at Oracle; event streaming with Apache Kafka and Apache Flink at Confluent; observability at Elastic; AI and developer tooling at AWS; and NoSQL and vector stores at Redis.

This foundation is exactly what separates AI demos that work on stage from AI systems that survive production.

Social Links

© 2018 - 2026 Ricardo Ferreira

Search is powered by Pagefind. Just hit CTRL+K or CMD+K to start searching.

Powered by Hugo with Dream and Devrel themes.